DeepSeek V4 with Million-Context Capacity, Fit Your Entire Novel In!
All Posts
- FeelFish Now Supports HarmonyOS PC
- FeelFish 4.0 Major Release 🐟 – Building a Professional-Grade Novel Writing Workbench
- A First Principles Approach to Web Novel Writing
- DeepSeek V4 Novel Writing Capability Review (II)
- Recruit Partners, Enjoy Cash Sharing
- DeepSeek V4 with Million-Context Capacity, Fit Your Entire Novel In!
- DeepSeek V4 Novel Writing Capability Evaluation (Part One)
- Novel Writing Enters the Multi-Agent Era — Introducing FeelFish 3.0
- FeelFish 2.13 is here with tons of new features! Come and try it out!
- FeelFish 2.13.0 Major Update: Cloud Drive + Knowledge Base + Semantic Search, Redefining the New Experience of AI Creation
- FeelFish 2.12.0 Released, Supports Generating Covers Based on Novel Content
- FeelFish Smart Planning Mode: Making AI Novel Writing More Planned
- Why Do AI-Written Novels Always Feel Repetitive? Can AI Really Write Compelling Stories?
- How to Avoid Plagiarism When Using AI to Write Novels
- FeelFish: Professional AI Novel Writing Agent Software
Upgrade to FeelFish 3.3.1 to experience the full-text Q&A feature with a million-token context!
The highly anticipated DeepSeek V4 has been released, supporting 1M tokens of context, allowing you to input over a million characters without any issues!
More importantly, DeepSeek's new retrieval technology ensures that even with such a large context, it can accurately identify and recall key information, unlike some models that claim to support a million tokens but struggle to deliver effective results.
But what does DeepSeek V4's true million-token context mean for novel writing?
The answer is even more powerful full-text Q&A.
While FeelFish previously supported semantic search using vector retrieval technology, the RAG retrieval method based on vector retrieval typically involved first matching parts of the content and then summarizing the answer from the matched content.
With million-token context, it truly allows the AI to process the entire text, enabling it to retrieve information from all the content without missing a single word.
To help the agents make better use of this capability and to help everyone save credits, FeelFish has introduced a new full-text Q&A feature:
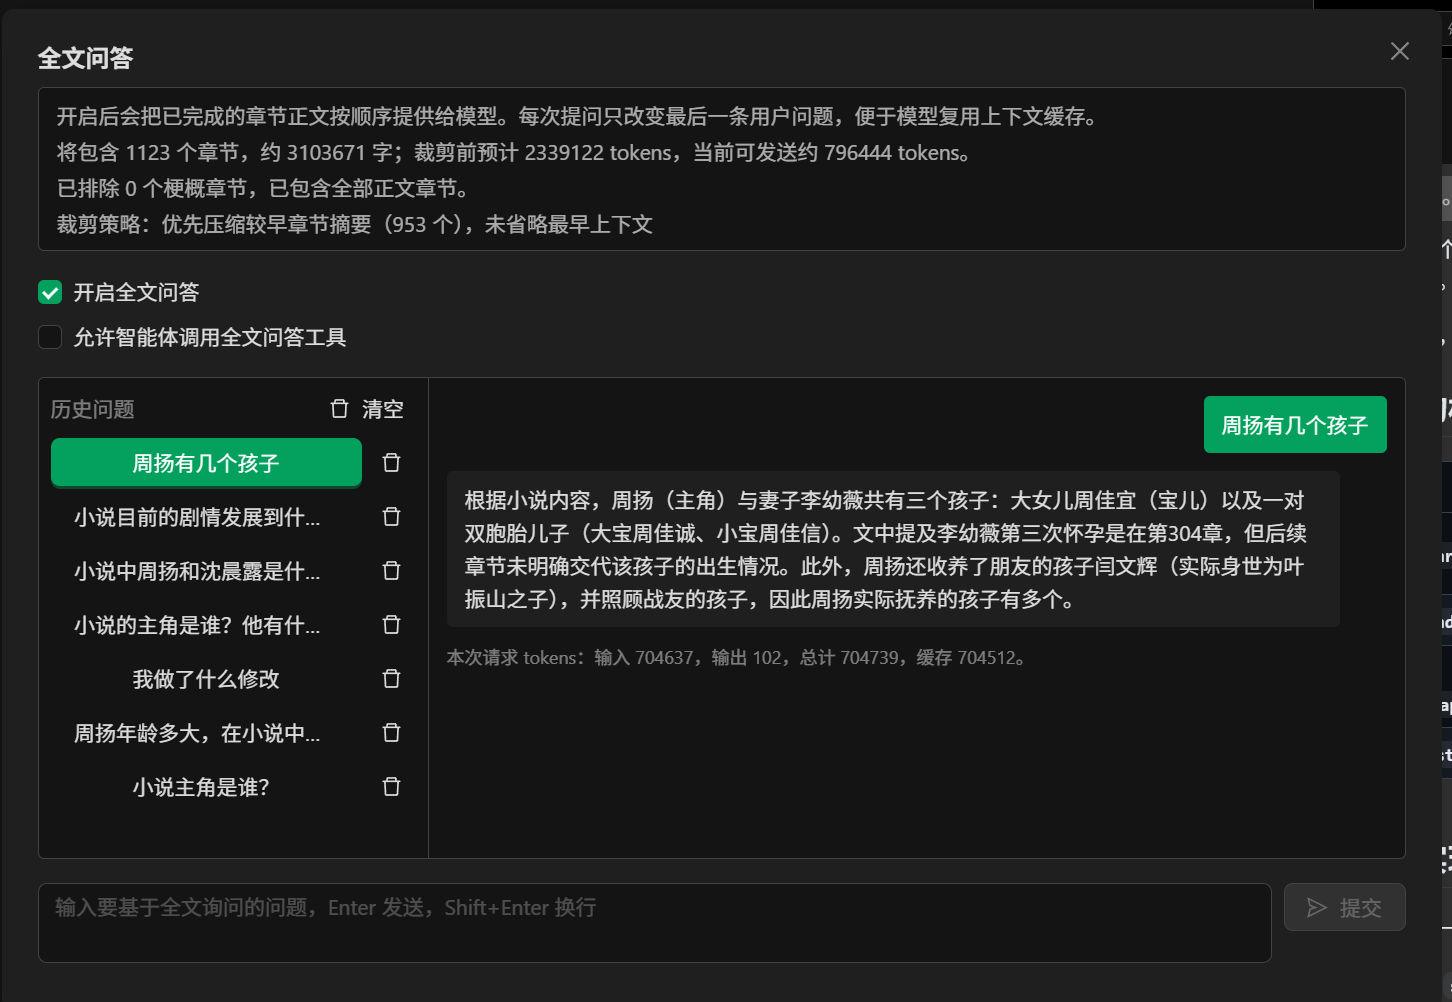
We have found that for novels up to a million words, we can provide excellent full-text Q&A. Even for novels that exceed a million words and reach up to three million words, we can still provide good answers after reasonable trimming.
Importantly, we leverage DeepSeek's powerful caching capabilities to minimize credit consumption. Even for a million-word Q&A, with cache optimization, a single Q&A session will consume less than 200,000 credits. For novels around 200,000 to 300,000 words, the consumption is even lower. Even if there are additions or modifications to the content, we strive to ensure the reliability of the cache and minimize credit consumption as much as possible.
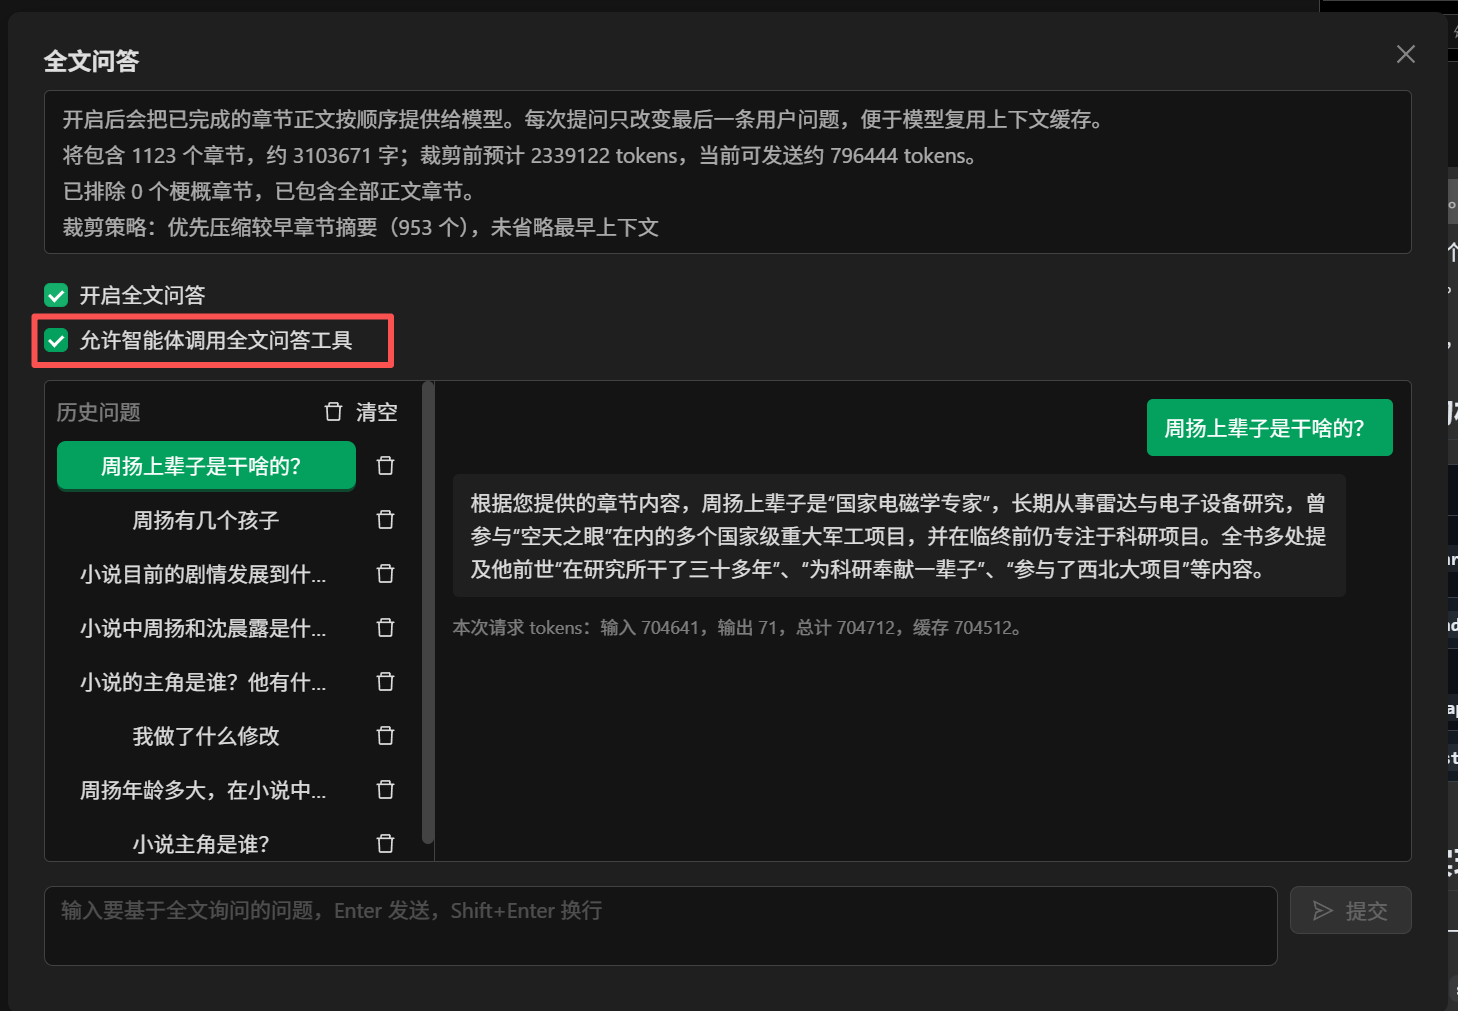
This capability has a significant use case: it can be invoked in an Agent for book analysis or to help the Agent better access global information about the novel during the creative process. Just check the option "Allow Agent to call full-text Q&A tool":
Here is an example:
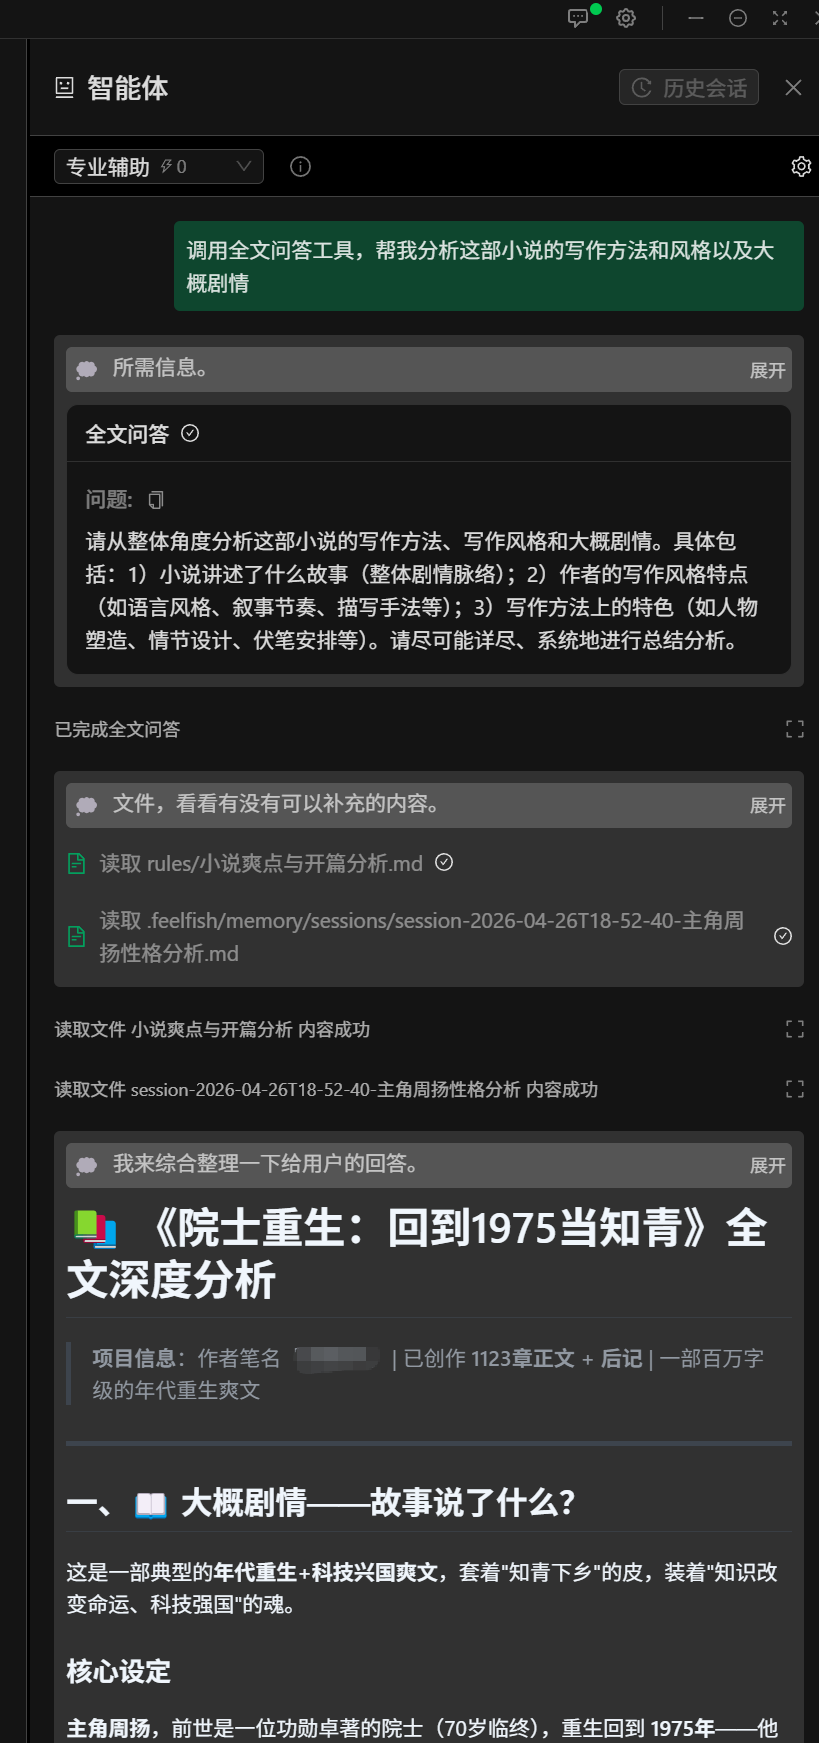
Come and give it a try! However, please note the credit consumption, especially for the first question without a cache, which will consume more credits. We recommend using DeepSeek-V4-Flash, which has stronger caching capabilities and is more cost-effective.
You can find the entry in the Toolbox: